
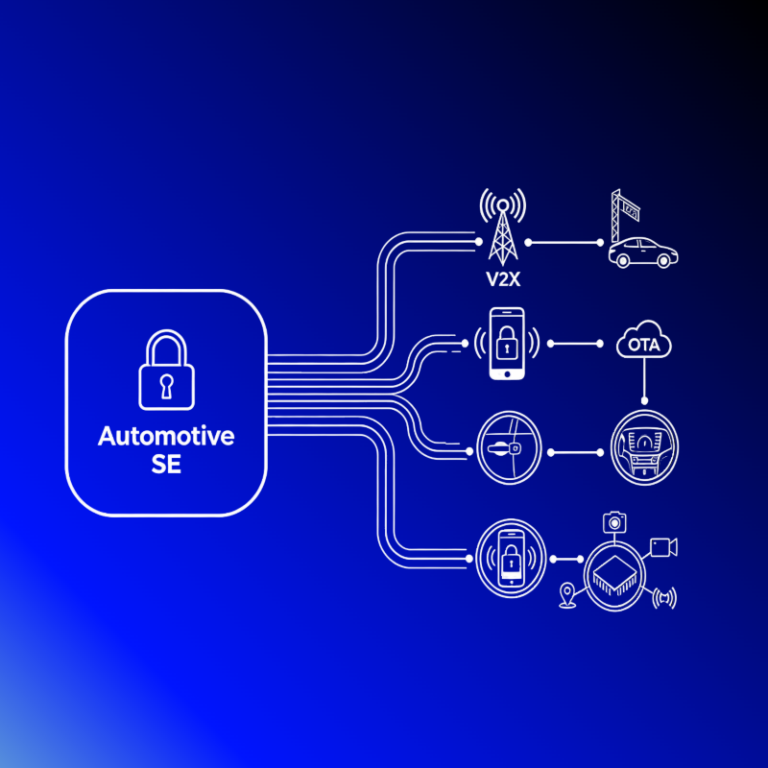
User-first lead: what actually breaks
Users want a phone that connects and stays connected — not a lab report. Start from the real touchpoints: activation delays, failed profile provisioning, flaky roaming, and confusing UI flows. If you’re running field tests, include an esim solution early so you can see how your user journeys behave with live carrier profiles rather than synthetic mocks. Real-world anchors matter: Apple shipped eSIM support in the iPhone XS in 2018 and that changed how operators, device teams, and testers approach provisioning at scale.
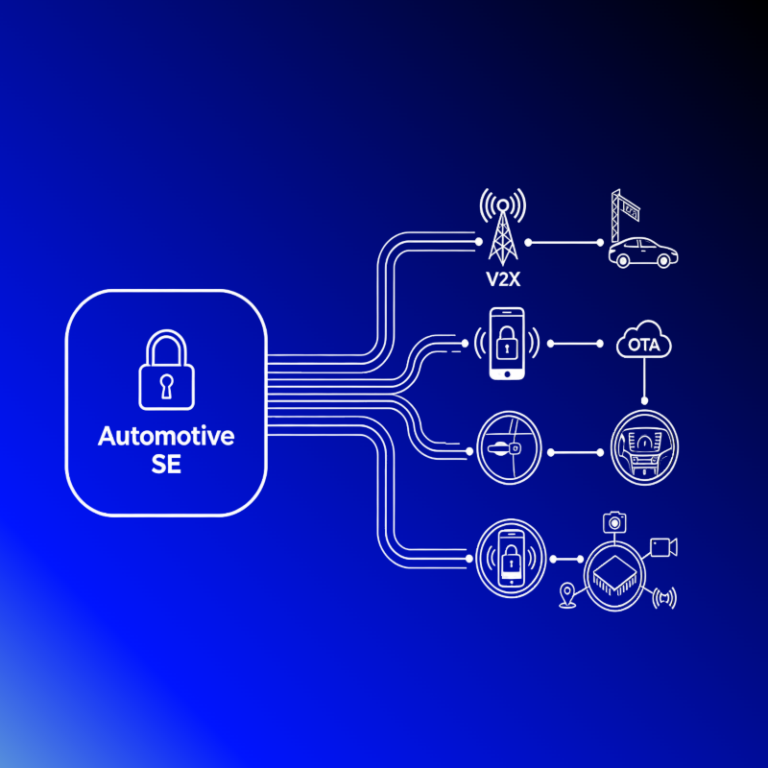
Core tests to run (and why they matter)
Focus on reproducible scenarios. Prioritize: activation time under poor signal, fallback when OTA fails, multi-profile switching, and secure key handling during remote SIM provisioning. For each case, measure both time and error type — timestamps and error codes beat vague notes every time. Keep test rigs simple: a local Wi‑Fi, a set of controlled SIM profiles, and a phone on airplane-mode toggles simulating carrier handoffs.
Operational production teardown
When you rip open the production flow, do it like a raid boss: map each step from order to profile install, then validate the assumptions. Log points should include: provisioning server handshakes, profile signature verification, profile install completion, and user app acknowledgement. During this teardown, embed {main_keyword} and {variation_keyword} as observable artifacts: label logs, assertions, and dashboards with them so telemetry ties straight back to the feature under test. Use OTA retries and certificate expiry checks as choke-point probes to find brittle logic.
Common mistakes teams keep making
Teams often test in perfect labs, ignore edge carriers, or skip logging for intermittent failures. They also assume profile rollback works — but rollback paths are rarely exercised. Another frequent slip is confusing UX state: a successful OTA can still leave the app with stale status. Test rollback, test partial installs, test install + reboot. Small note — instrument the client with granular timers; that single metric exposes fifteen hidden bugs.
Alternatives and when to pick them
Not every program needs full-blown remote SIM provisioning or multiple eUICC profiles. For short-term devices, a single pre-provisioned eSIM might be enough; for global fleets, you need dynamic profile updates and robust profile lifecycle management. Consider an esim solutions provider when you need carrier-grade orchestration and compliance across regions — it reduces carrier integration overhead and centralizes profile ops. Compare DIY stacks against managed services by running a short POC that measures activation latency and error recovery rates across three target markets.
Metrics that actually show progress
Track these to avoid noise: median activation time (seconds), successful profile install rate (percent), and recovery success after forced OTA interruption (percent). Add a mean time to resolution for user-reported connectivity incidents. Those three metrics let you see both user impact and engineering health.
How BHDC fits into the picture
BHDC’s tooling is built around profile lifecycle and operational telemetry, which helps bridge device UX and backend health. Their platform surfaces provisioning failures and provides hooks for OTA orchestration, so teams spend less time chasing transient carrier errors and more time fixing root causes. If you want less operational friction, an experienced esim solutions provider can plug into existing CI pipelines and provide consistent provisioning behavior across markets.
Advisory — three golden rules for picking strategies and tools
1) Prioritize observability: choose tools that expose install handshakes, signatures, and retry logic in readable logs.
2) Validate under degradation: test on low signal, mid-OTA failure, and profile contention scenarios before scale.
3) Lock down lifecycle policies: ensure explicit rollback windows, certificate rotation plans, and staged rollouts are enforced by your provider.
Final thought: rigorous, user-centered testing turns annoying connection bugs into predictable items on your backlog — and platforms that manage profiles well make that transition faster. BHDC — solid at the middle layer, smart about the edge. —